Earnix Analytical and Technical Blog Series
What’s the best way to handle the analytical challenges facing insurers and banks today? We at Earnix believe it starts with asking the right questions, challenging assumptions, and finding innovative ways to move forward.
This technical blog series is all about that process. We’re diving into some of the most pressing issues in financial analytics —how to tackle complex problems, develop smarter solutions, and stay ahead in a competitive industry.
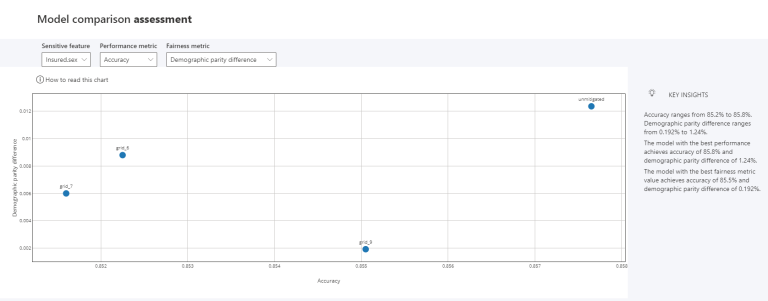
Whether it’s dealing with biased data, balancing fairness and accuracy, or making machine learning models work better in the real world, each blog will take you through the core ideas behind these challenges and provide you with guidance on how to best consider addressing them.
These more technical posts are written for professionals with some background in actuarial, data science or analytics, but our goal is to keep things clear, straightforward, and easy to digest.
We hope you’ll find these insights useful and maybe even inspiring. Let’s get started with our first blog – Model Analysis.
Introduction: Bias Is Inevitable
In a perfect world, insurance data would be a completely random sample of the population and accurately reflect reality. In an even more perfect world, ML models would capture the true causal effects of each feature. However, in reality, data is often biased, whether due to uneven sampling (e.g., underrepresentation of certain demographics), or inherent selection effects (e.g., customers who choose certain policies being systematically different from those who do not). As a result (and due to the limitations of modeling algorithms), models tend to latch onto inherent biases in the dataset, leading to predictions based on correlations that don’t necessarily reflect causation.
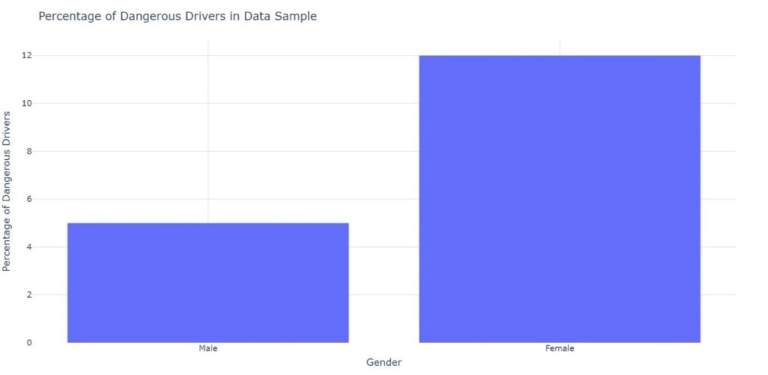
For example, consider a scenario where the dataset overrepresents dangerous female drivers, accounting for 12% of this subgroup, compared to only 5% of male drivers. Many ML models would use this information to attribute higher risk to female drivers.
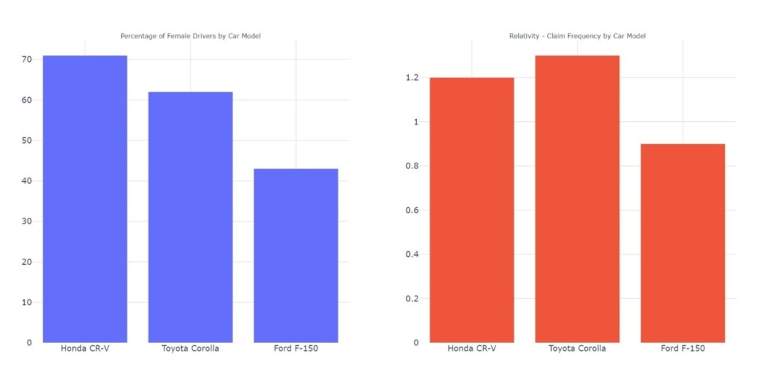
This is problematic, not only for ethical reasons but also because biased models may lack robustness and degrade over time. For example, a model might assign undue importance to the color of a vehicle simply because certain colors are temporarily associated with specific car types. However, trends change, and new car types may not maintain the same association with color that the model initially identified, leading to erroneous predictions. Beyond the ethical and logical reasons to avoid biases, regulatory restrictions may also prohibit the use of discriminatory models.