Earnix Analytical and Technical Blog Series
How can insurers and banks tackle today’s toughest analytical challenges? At Earnix, we believe it starts with asking the right questions, challenging assumptions, and finding better ways forward.
In this blog series, we explore key issues in financial analytics, addressing complex problems, improving models, and staying competitive. Our first posts covered Model Analysis and Auto-XGBoost.
These technical posts are designed for professionals in actuarial science, data science, and analytics, with a focus on clarity and practical insights. The third topic of the series, which we will cover today, is Smart Grouping of categorical features for GLMs – a feature already implemented in our product as part of our Auto-GLM solution. Let’s get started.
Introduction: Categorical Features Make Life Harder
One of the most important challenges a model-maker must tackle when creating a model is how to treat categorical features. This is specifically relevant for General Linear Models, but it’s also a non-trivial question for other types of ML models. Essentially, models are complex combinations of mathematical formulas, so they can’t directly use “words”.
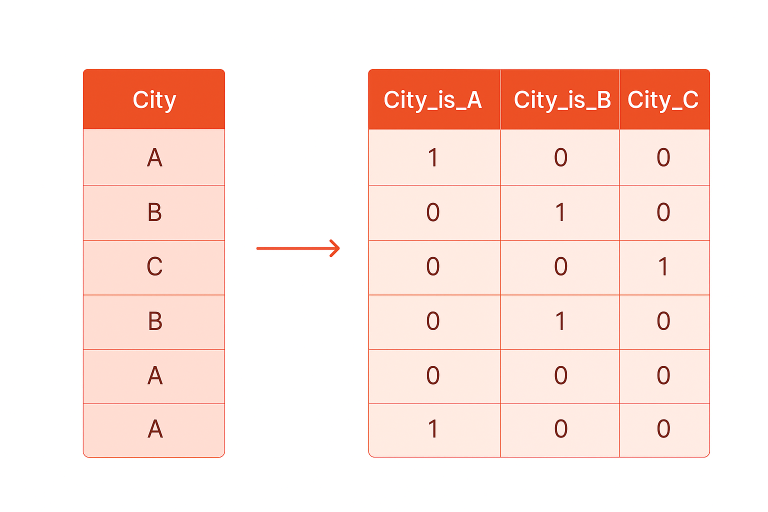
The most common approach is to use One-Hot Encoding – splitting a categorical feature with n categories into n-1 boolean features, and assigning 0/1 labels depending on the match of each feature to the category it represents. Commonly, we call them is_category_i for 1 ≤ i ≤ n-1 (leaving one out for the intercept).